Wed, Sep 2, 202639:06RoutingCoding agentsInference
Your Harness Is the Other Half of the Model
Colin McNamara shares what tuning open models on one GH200 taught him about the serving stack.
Takeaways
- His GH200, named Athena and reached over WireGuard, runs a Qwen3.8-27B-FP8 model alongside other jobs, including Qwen3Guard for routing and prompt-injection checks; OpenCode, Codex and Claude Code connect to vLLM-SR running on his laptop.
- Memory bandwidth, not tensor cores, was the limit: the KV cache grows with context, and the card has three memory tiers (fast GPU memory, Grace CPU DRAM and NVMe).
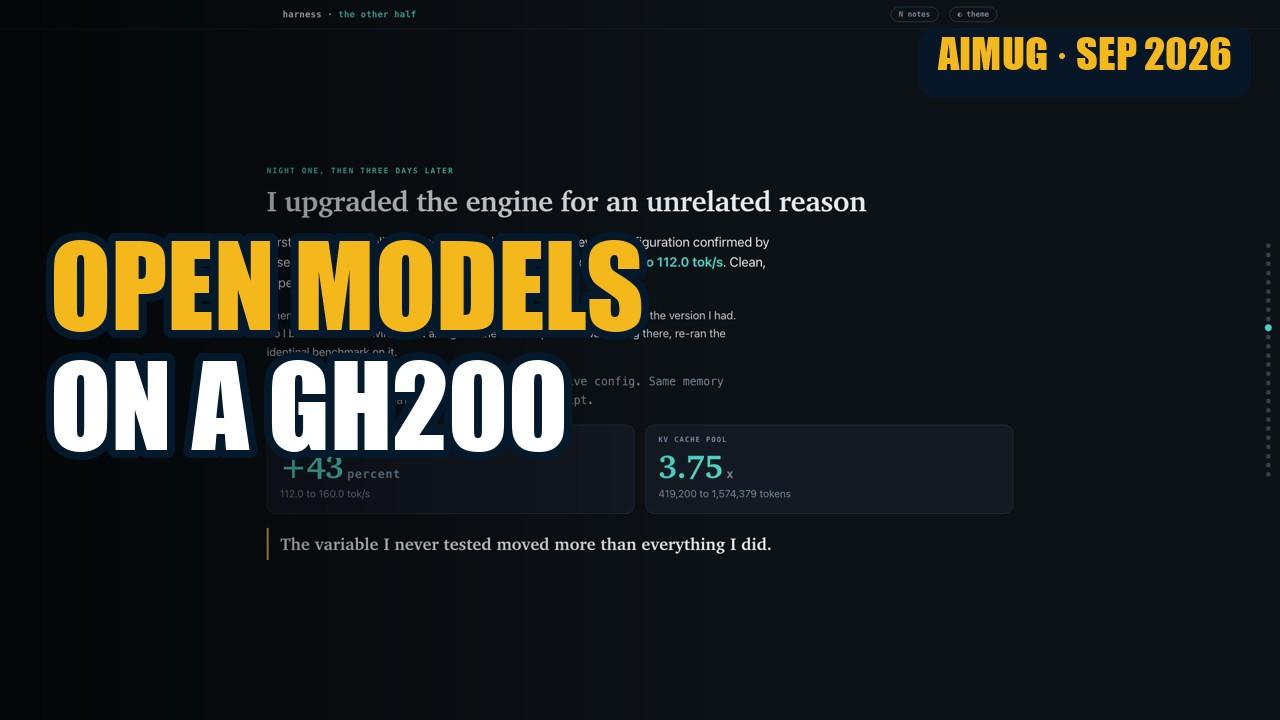
- He explores grouped queries and speculative decoding with MTP; upgrading vLLM raised Qwen3.8's decode speed by about 43%, from 112 to 160 tokens a second, and he found the engine did not exploit the model's mix of linear and full attention.
- Moving mixture-of-experts layers to the CPU ran a 154 GB DeepSeek V4 model on a 96 GB card at about 73 tokens per second, with trade-offs.
- Test one variable at a time, overnight, and retest after each change; vLLM-SR can route by complexity and send suspected prompt injection to its own route.
Transcript
Transcript coming.